SGLang SSD专家包:消费级硬件运行DeepSeek-V4-Flash与Kimi-K3

SGLang SSD专家包:消费级硬件运行DeepSeek-V4-Flash与Kimi-K3

引言:将VRAM问题转化为存储问题

DeepSeek-V4-Flash和Kimi-K3的总参数量远超单张消费级GPU的VRAM容量。传统部署需多GPU或数百GB主机内存,门槛极高。SGLang的SSD Expert Pack路径将未激活的专家权重保留在NVMe SSD上,仅路由选中的专家才从SSD加载至GPU缓存。
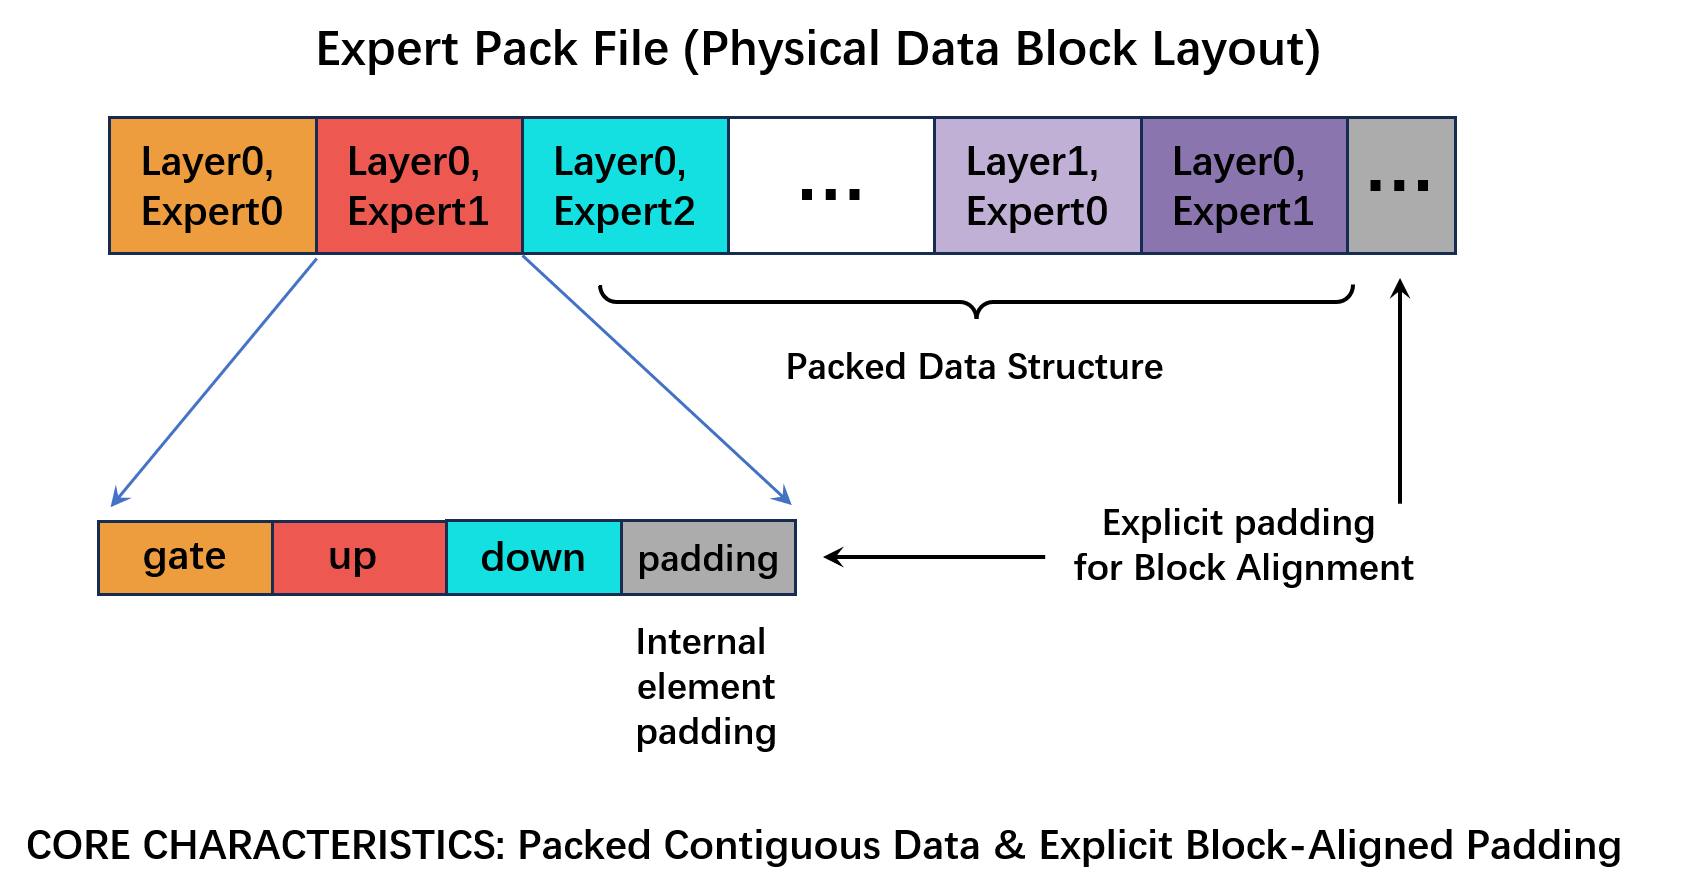
Expert Pack physical data block layout with contiguous expert byte-streams and explicit block-aligned padding

容量成本对比

下图以对数尺度展示了VRAM、DRAM与SSD的容量成本差异,清晰说明SSD作为后备层可大幅降低硬件门槛。
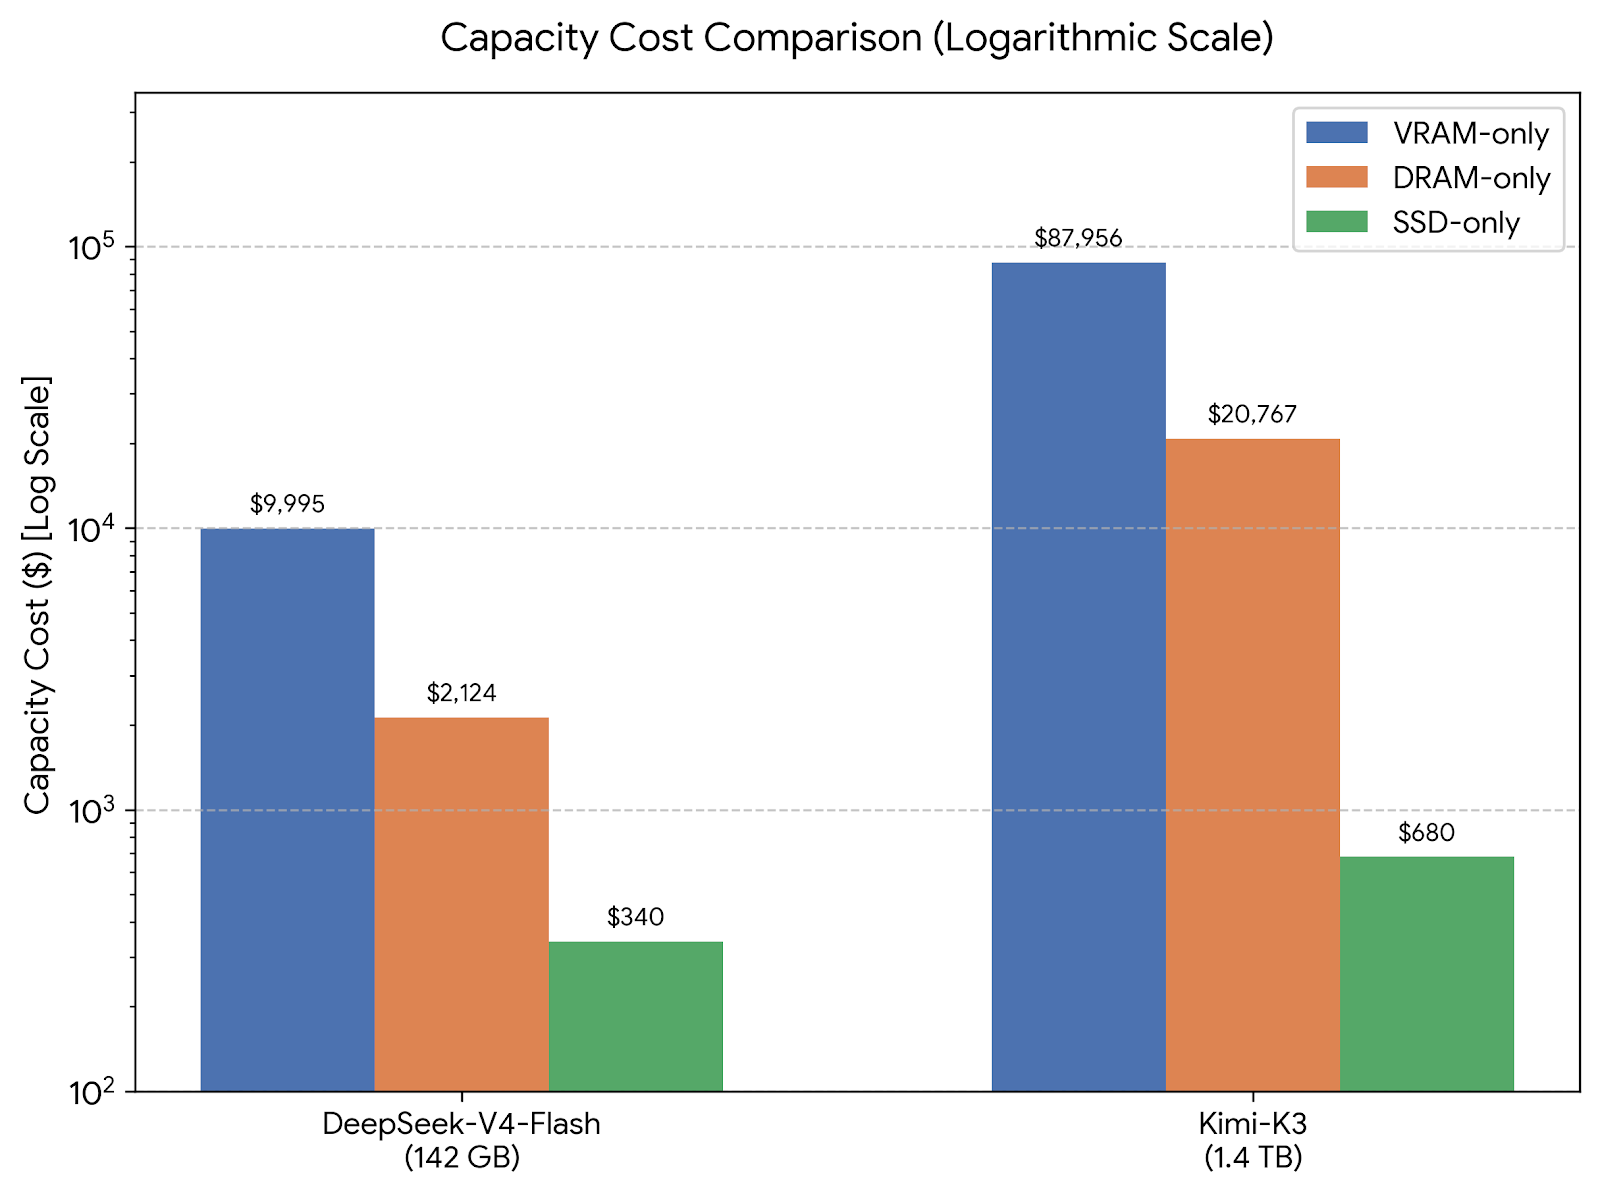
Capacity cost comparison for DeepSeek-V4-Flash and Kimi-K3 on a logarithmic scale

传统文件读取路径的局限

传统GGUF加载需经过页缓存到固定内存的同步拷贝,再进行异步H2D传输。
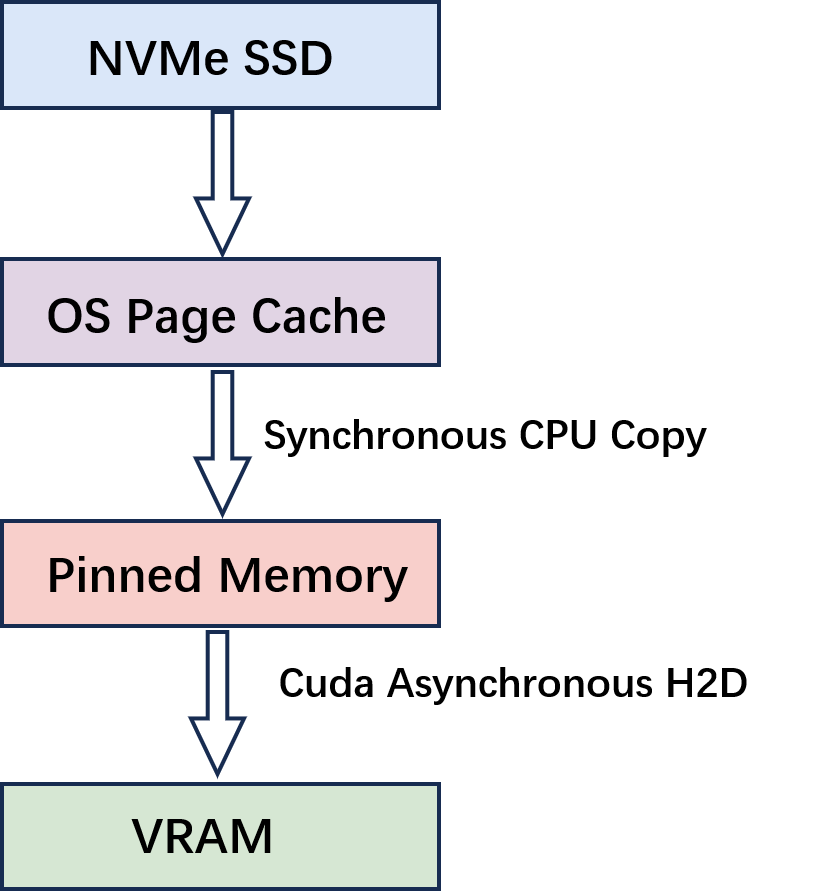
Traditional file-read path: a synchronous page-cache-to-pinned-memory copy followed by asynchronous H2D

Expert Pack直接I/O优化路径

Expert Pack采用对齐固定主机缓冲,直接馈送GPU专家缓存,避免多余拷贝。
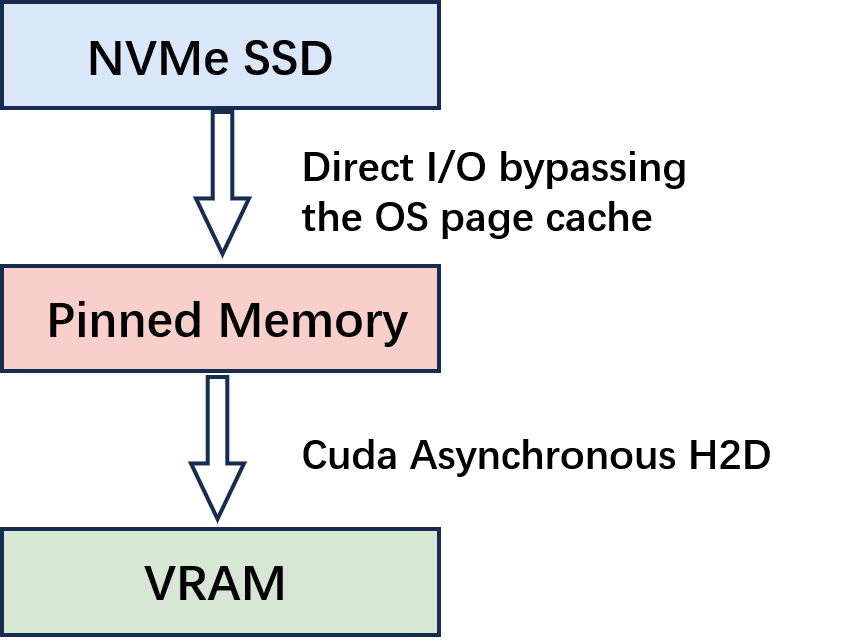
Expert Pack direct-I/O path: an aligned pinned host buffer feeds the GPU expert cache before MoE computation

性能对比结果

DeepSeek-V4-Flash在Alpaca和MMLU上的预填充与解码速率对比显示SGLang方案显著优于基线。
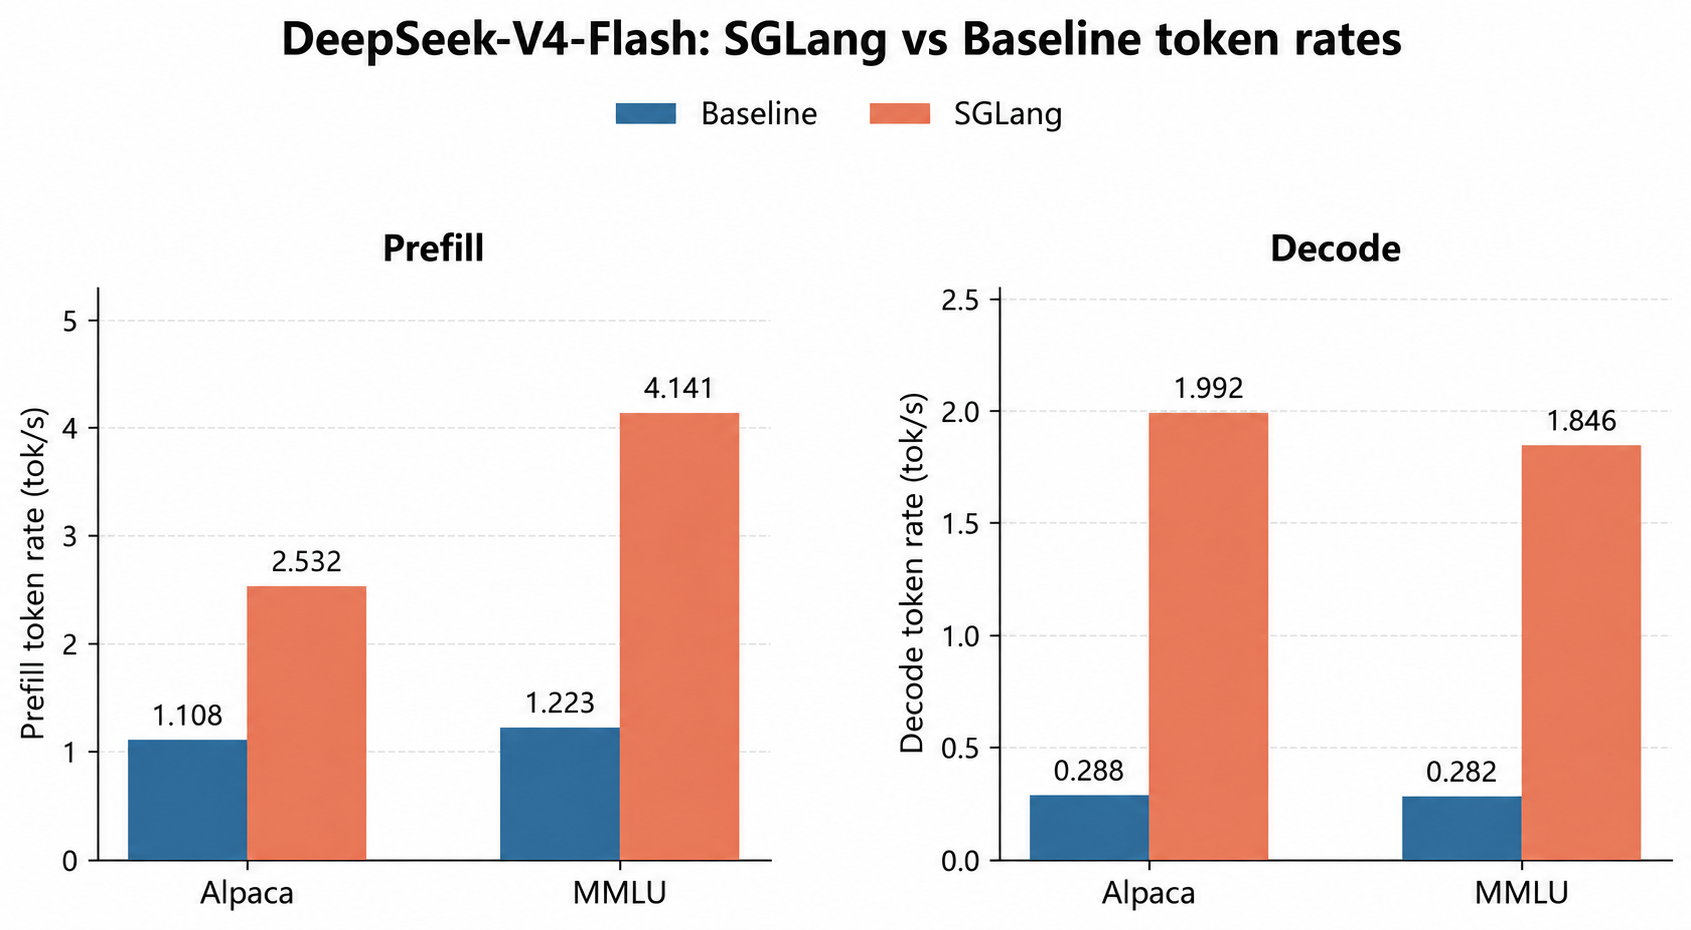
DeepSeek-V4-Flash SGLang versus Baseline prefill and decode token rates for Alpaca and MMLU

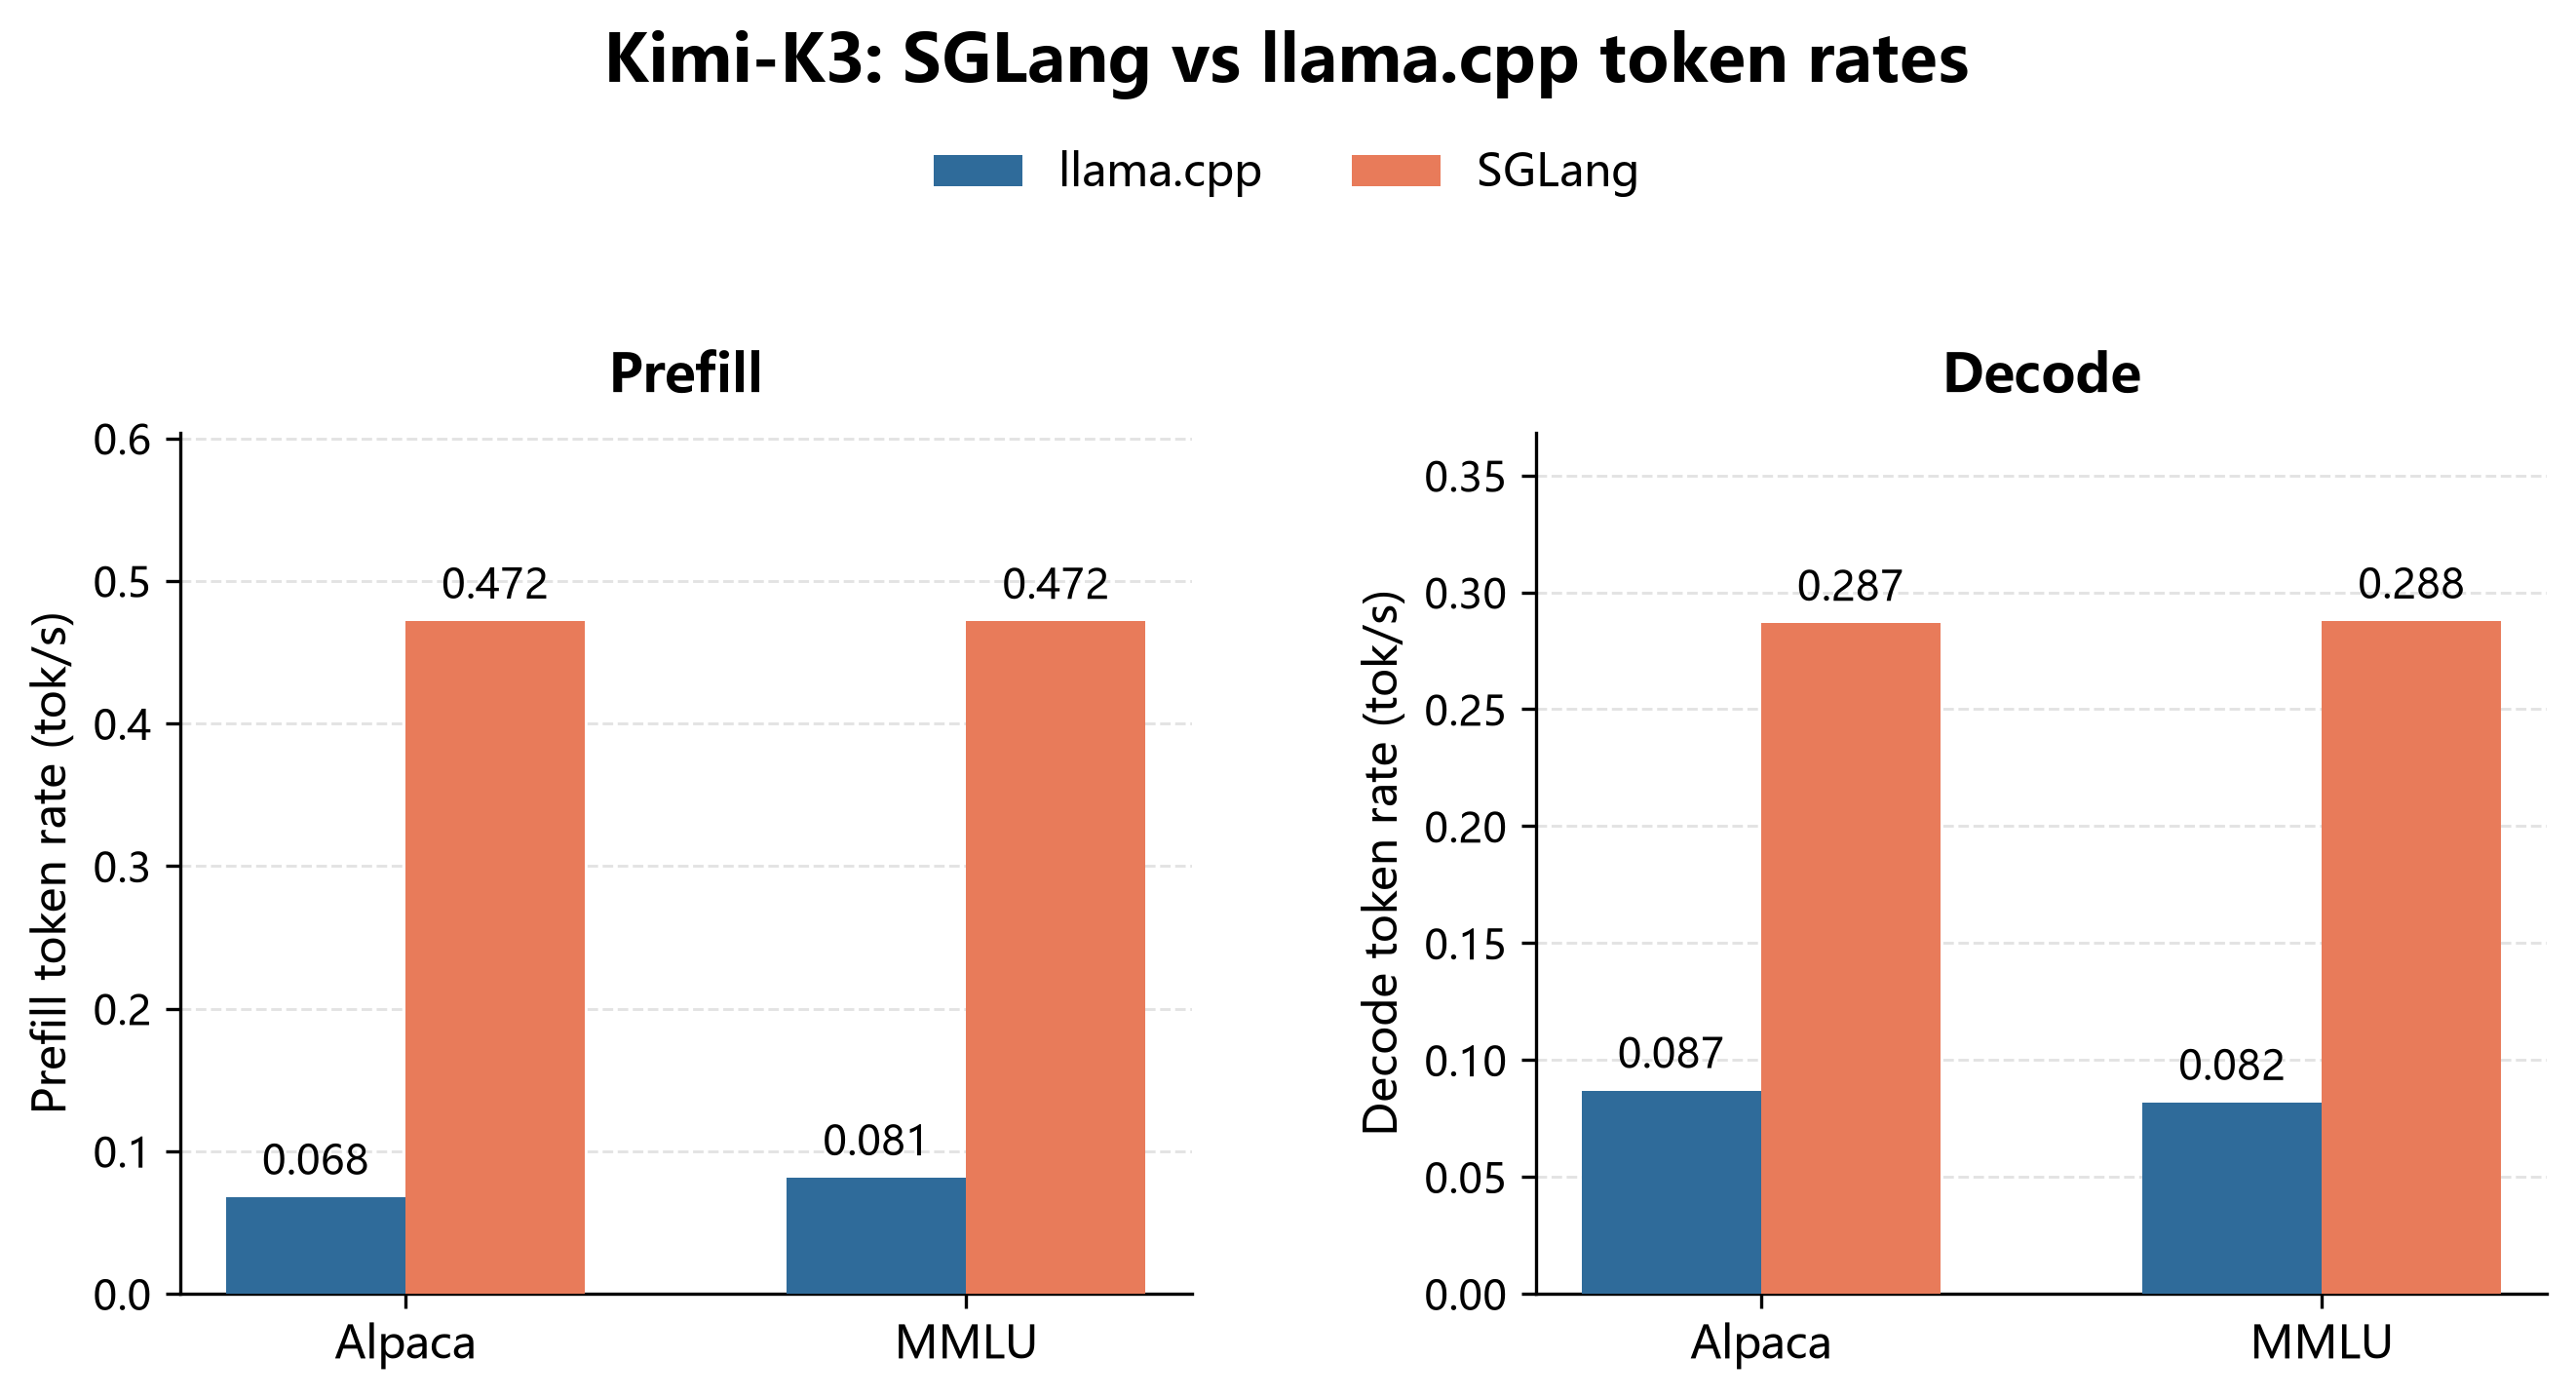
Kimi-K3同样在SGLang与llama.cpp之间展现明显优势。

Kimi-K3 SGLang versus llama.cpp prefill and decode token rates for Alpaca and MMLU

缓存命中率与SSD流量

DeepSeek-V4-Flash的VRAM缓存命中率及每token平均SSD流量数据证明方案高效。
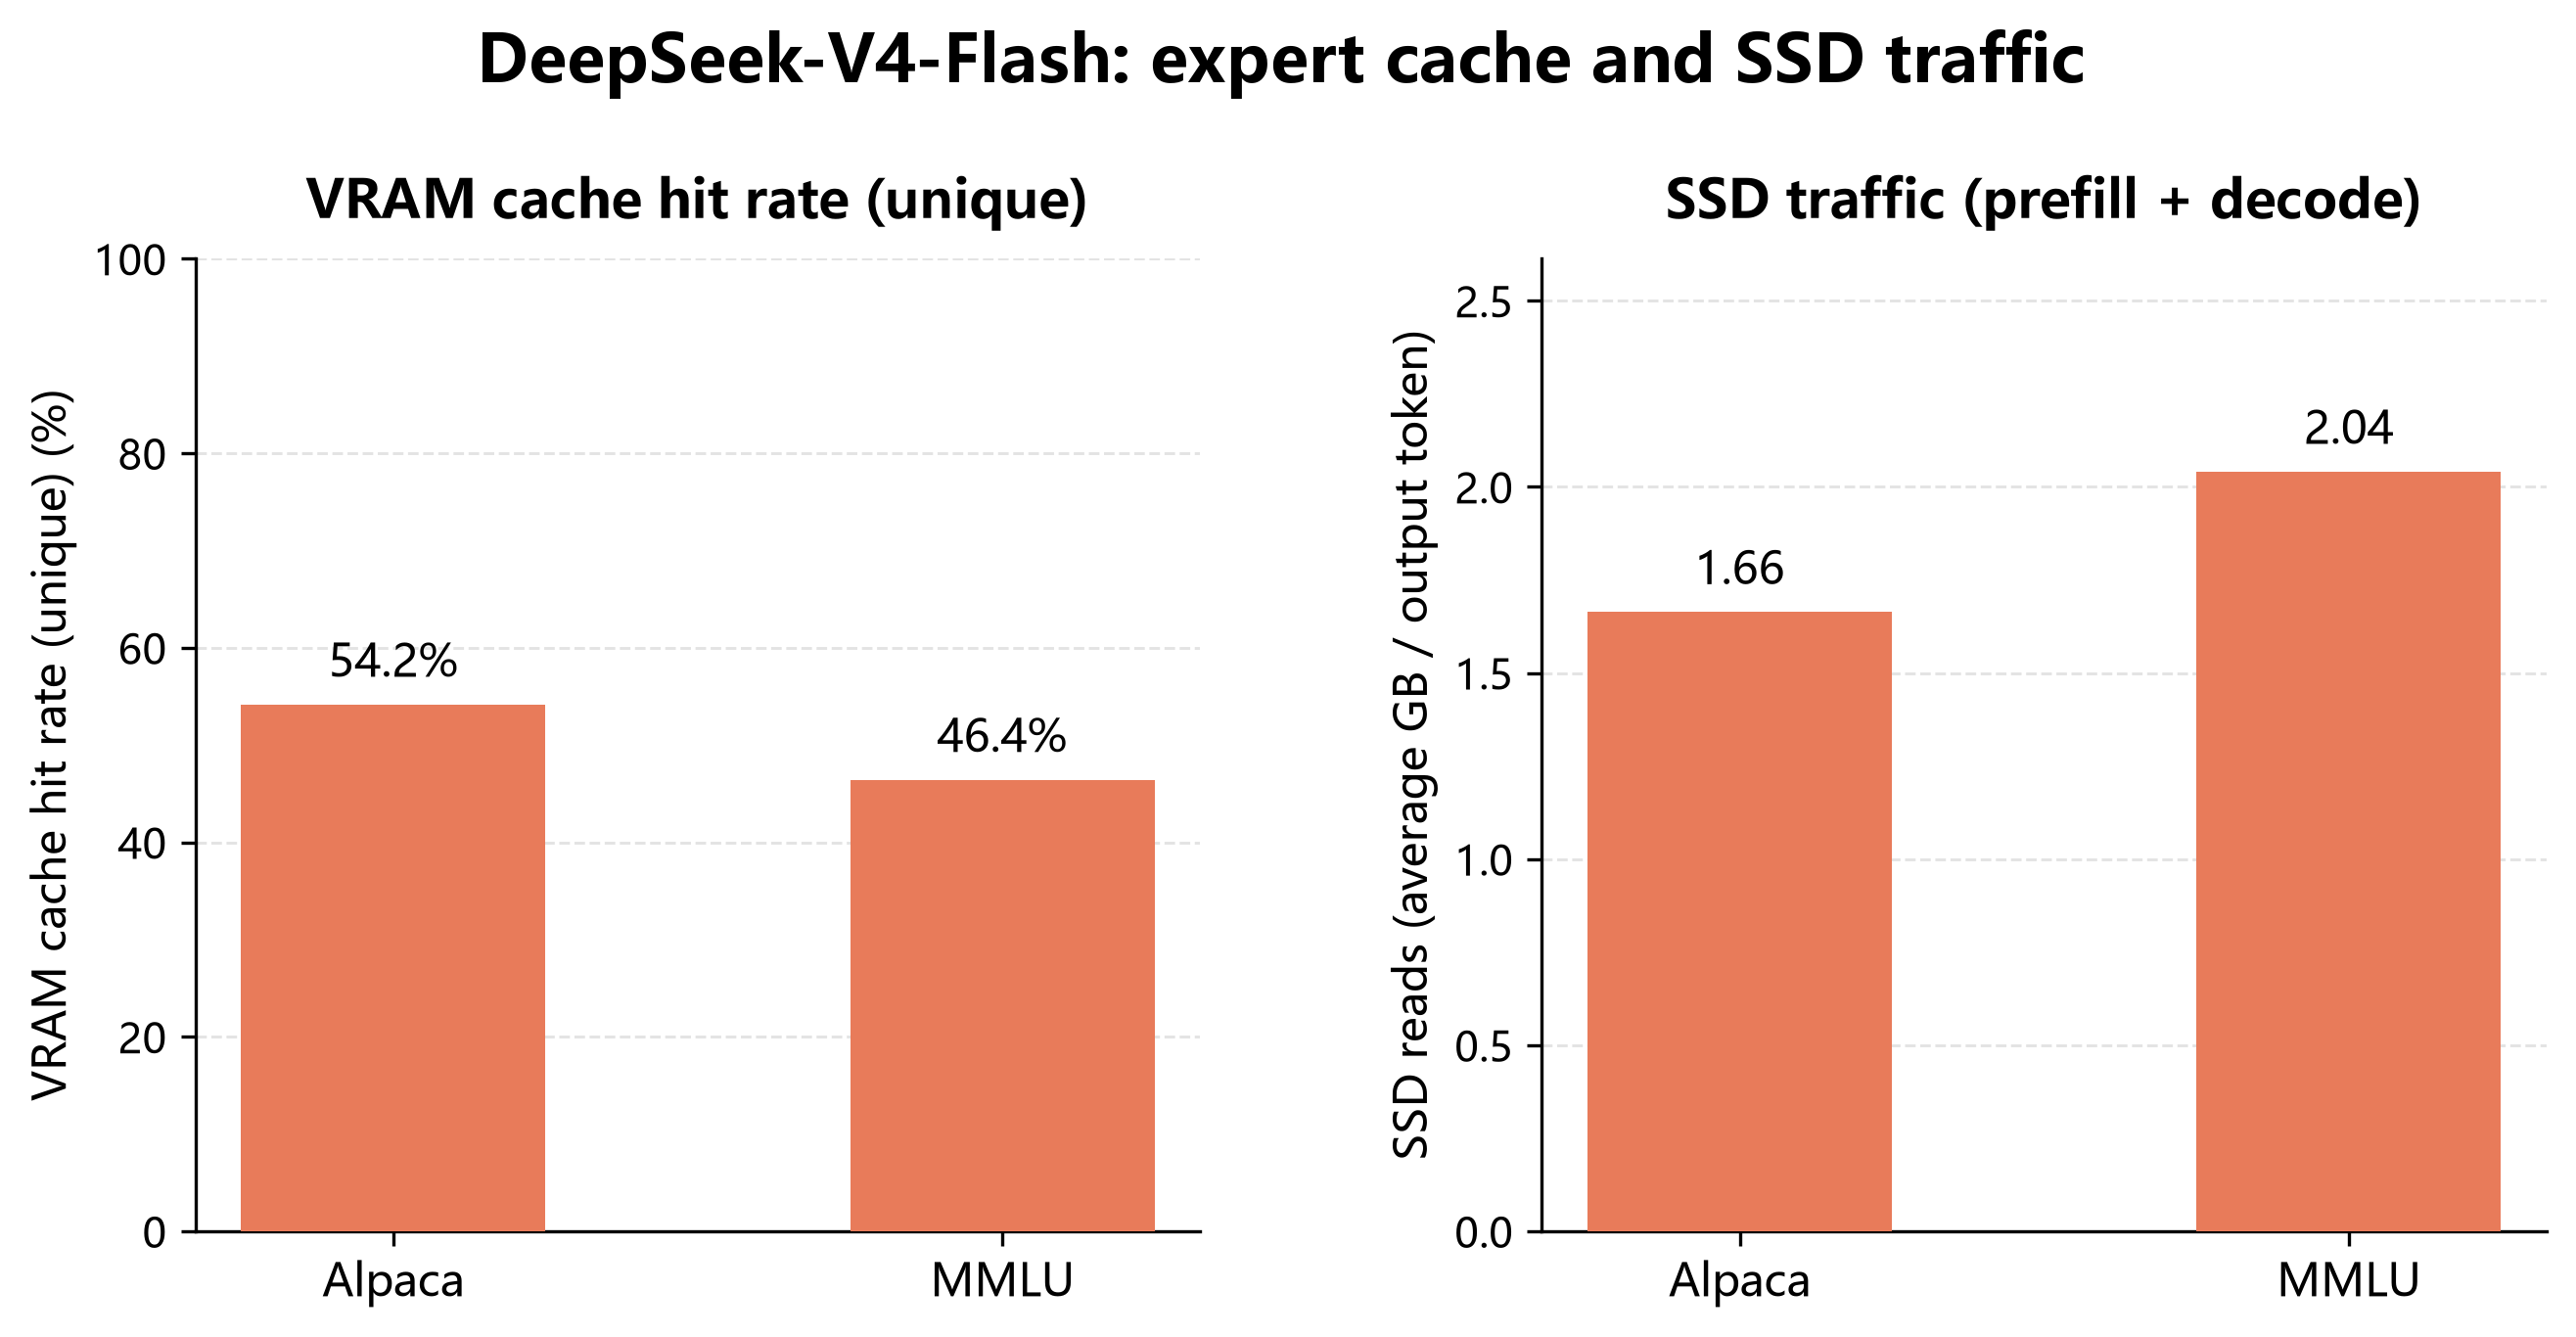
DeepSeek-V4-Flash SGLang unique VRAM cache hit rate and mean SSD traffic per generated token

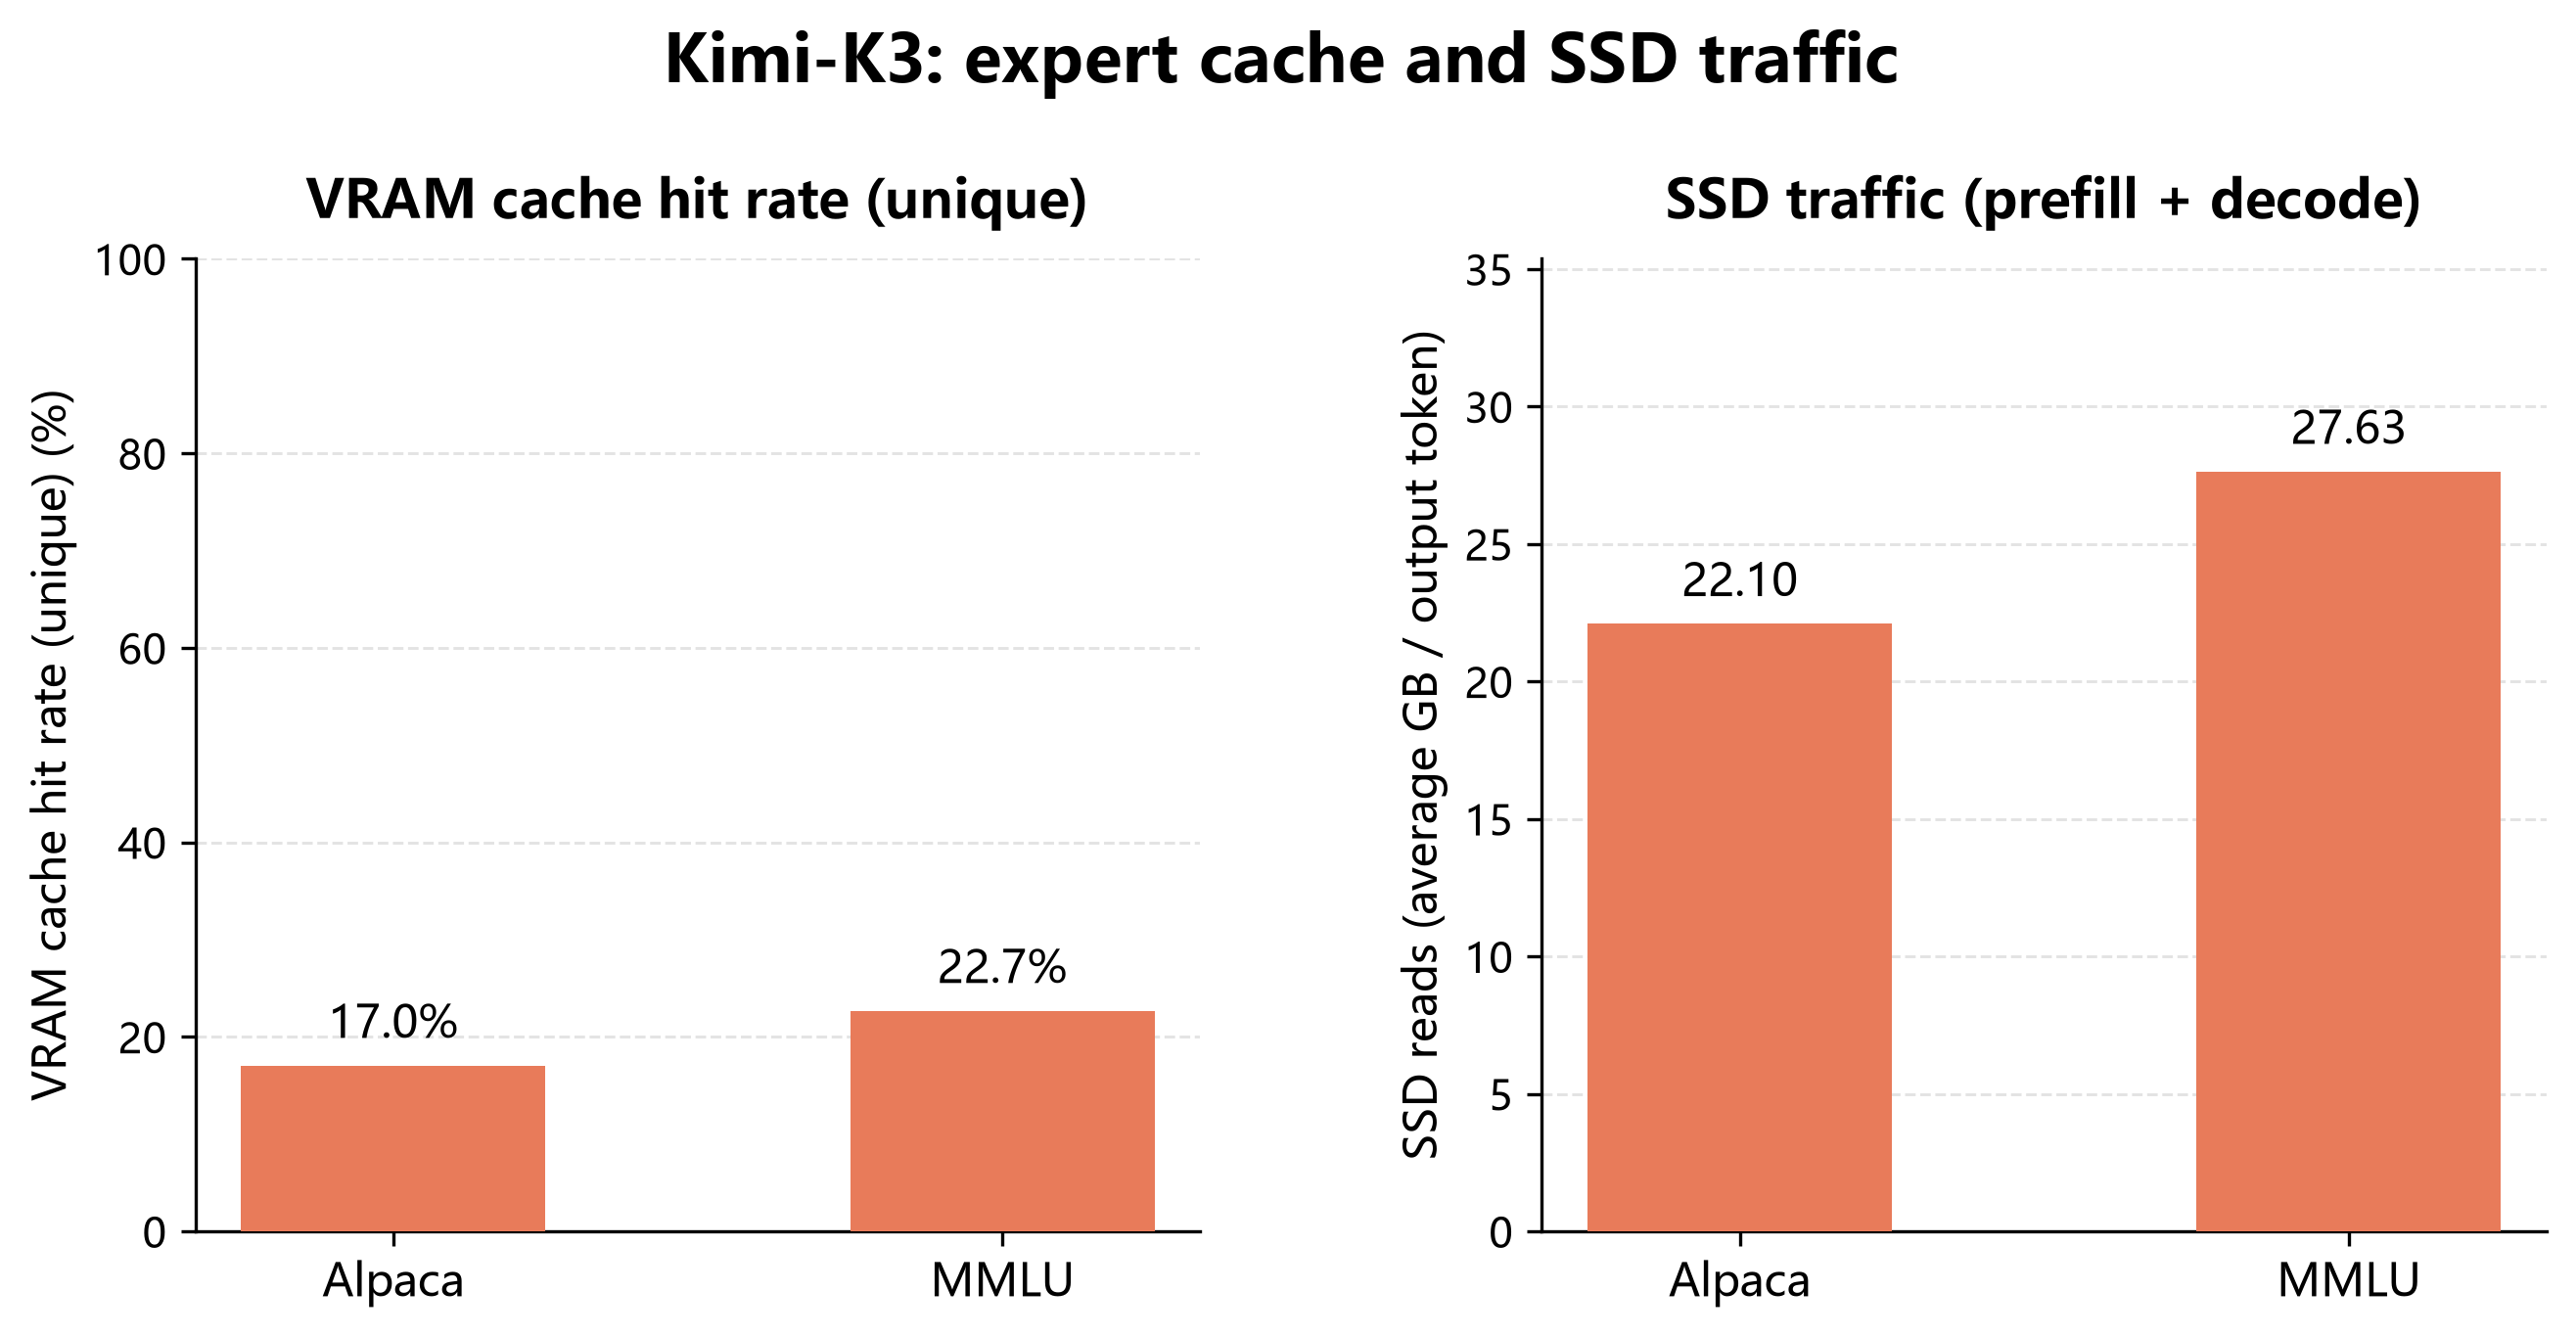
Kimi-K3的对应指标同样验证了SSD后备层的实用性。

Kimi-K3 SGLang unique VRAM cache hit rate and mean SSD traffic per generated token