
DeepSeek 开源了其自用推理引擎 DeepInfer 以及配套 kernels,为 DeepSeek-V4.1-Flash 的推理速度树立了新的参照。SGLang 团队随后在相同硬件上,使用 DeepInfer 自己的 benchmark 对 SGLang 进行了对比测试。结论很直接:SGLang 不仅集成了 DeepInfer 的关键优化,在多项指标上还做到持平或领先,同时提供 DeepInfer 发布版中尚未包含的完整 serving 系统能力。
核心结论
- 在 DeepInfer 自家基准上持平或领先。 在 4x GB300 与 4x B300 上,SGLang 的 prefill 吞吐最高达到 DeepInfer 的 1.04x;在 64x GB300 上,decode step 最多缩短 7.4%;其余测试点差距均在 1% 内。
- DeepInfer 的优化已进入 SGLang。 SGLang main 分支已支持 DeepSeek kernels,包括 Mega 系列、DSpark speculative decoding、SWA bounded replay,以及两种 Engram placement。
- SGLang 是完整推理服务系统。 DeepInfer README 中列出的 KV cache system、prefill/decode disaggregation、跨副本 load balancing 等未随其发布版提供的能力,SGLang 均已内置。
SGLang 集成了哪些能力
SGLang 从支持 V4.1 的第一天起,就已运行 SWA bounded replay 和 host-memory Engram tables。随后,SGLang 继续加入 DeepSeek 的 Mega kernels、跨 GPU 拆分 Engram tables 的 direct peer reads,以及更多执行层优化。
DeepSeek kernels
SGLang 集成了 FlashMLA、DeepGEMM、DeepEP、DeepSelect、TileLang kernels,以及 Mega 系列:MegaAttention、MegaMoE、MegaGate 和 Mega-mHC。其中,MegaMoE 将 token dispatch、expert GEMMs 与 combine 融合到一个 kernel 中;MegaAttention 则是 B300 与 GB300 上的默认 attention 路径,覆盖单机、prefill server 与 decode server。
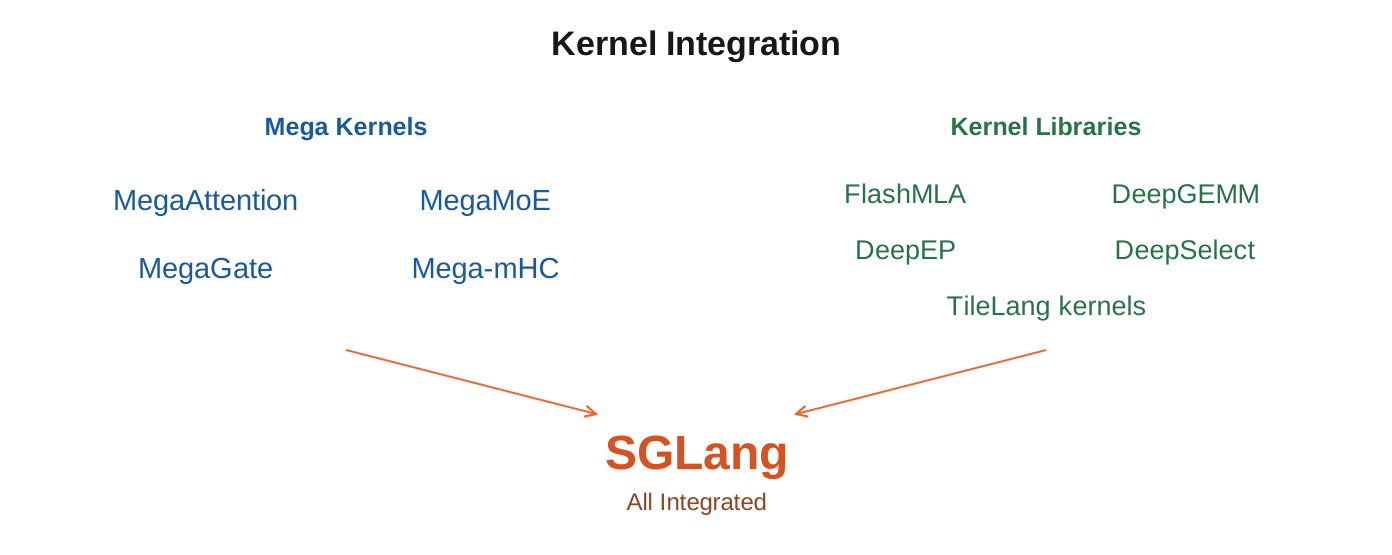
图 1:SGLang 中集成的 kernels。
Parallelism
SGLang 在 prefill 与 decode 阶段都采用 DP attention 加 expert parallelism(DEP)。本次 benchmark 中,prefill 使用 DEP4,decode 则在 64 张 GB300 GPU 上使用 DEP64。此外,SGLang 还支持 EPLB,用于在 wide-EP 部署中平衡 expert load。
DSpark speculative decoding
SGLang 可运行 checkpoint 中的 DSpark draft model,先提出一组候选 tokens,再由 target model 一次性验证,从而减少生成回复所需的 target-model forward pass 次数。
SWA bounded replay
在 decoder replay 中,后段 decoder layers 只处理 prompt 末尾的 128 个 tokens,而更早的 source layers 仍会处理完整 prompt。对于 prefix-cache hit,encoder replay 会利用最后 128 个已缓存 tokens 重建缺失的 sliding-window KV。
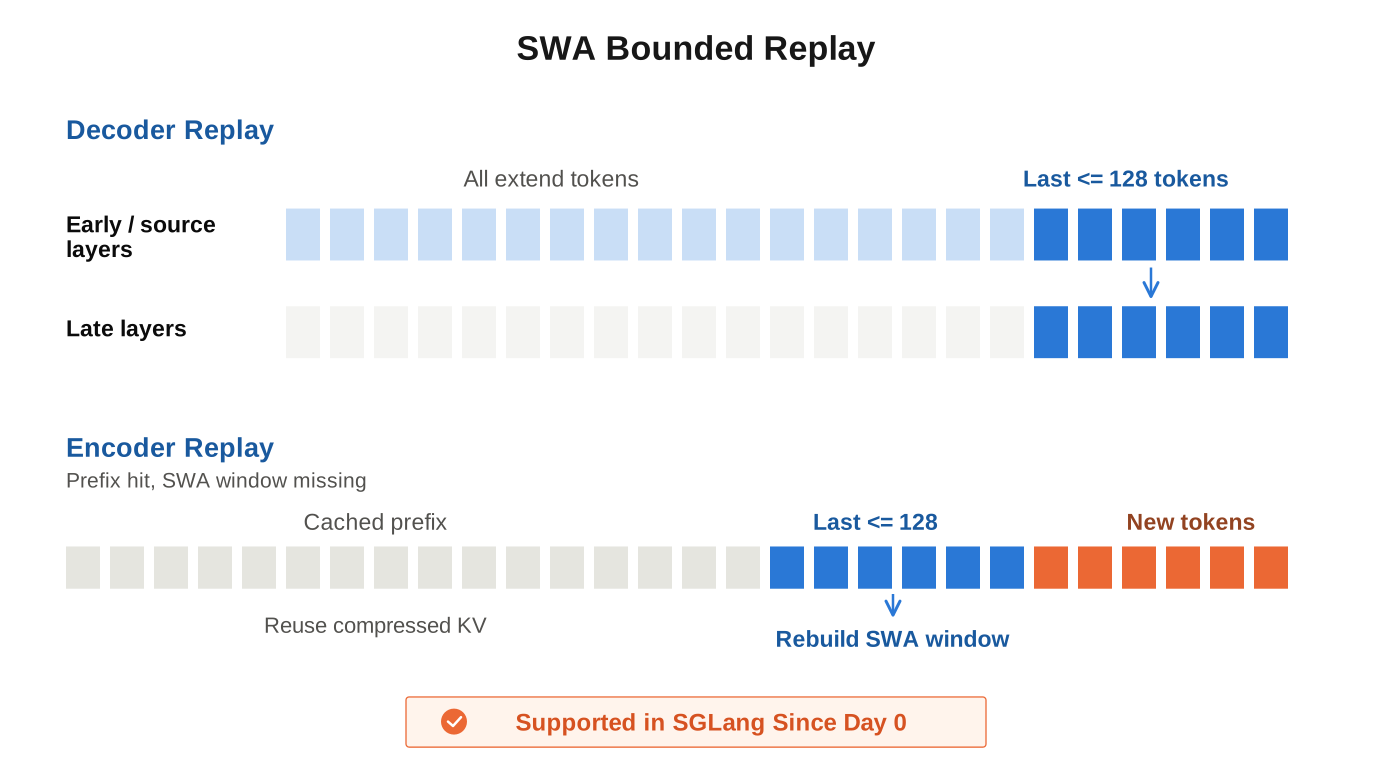
图 2:SWA bounded replay,包括 decoder replay 与 encoder replay。
Engram placement
DeepInfer 支持将 Engram tables 放在 host memory 或 device memory,SGLang 同样支持这两种模式。设置 SGLANG_ENABLE_DSV41_ENGRAM_HOST_TABLE=1 时,每个节点在 host memory 中保存一份表,从而为 KV cache 留出更多 HBM。设置 SGLANG_OPT_DSV41_ENGRAM_PEER_SHARDS=1 时,表会被拆分到多张 GPU 上,每张 GPU 通过 NVLink 直接从 peer GPU 读取所需 rows,lookup 前后无需 all-gather 或 reduce-scatter。
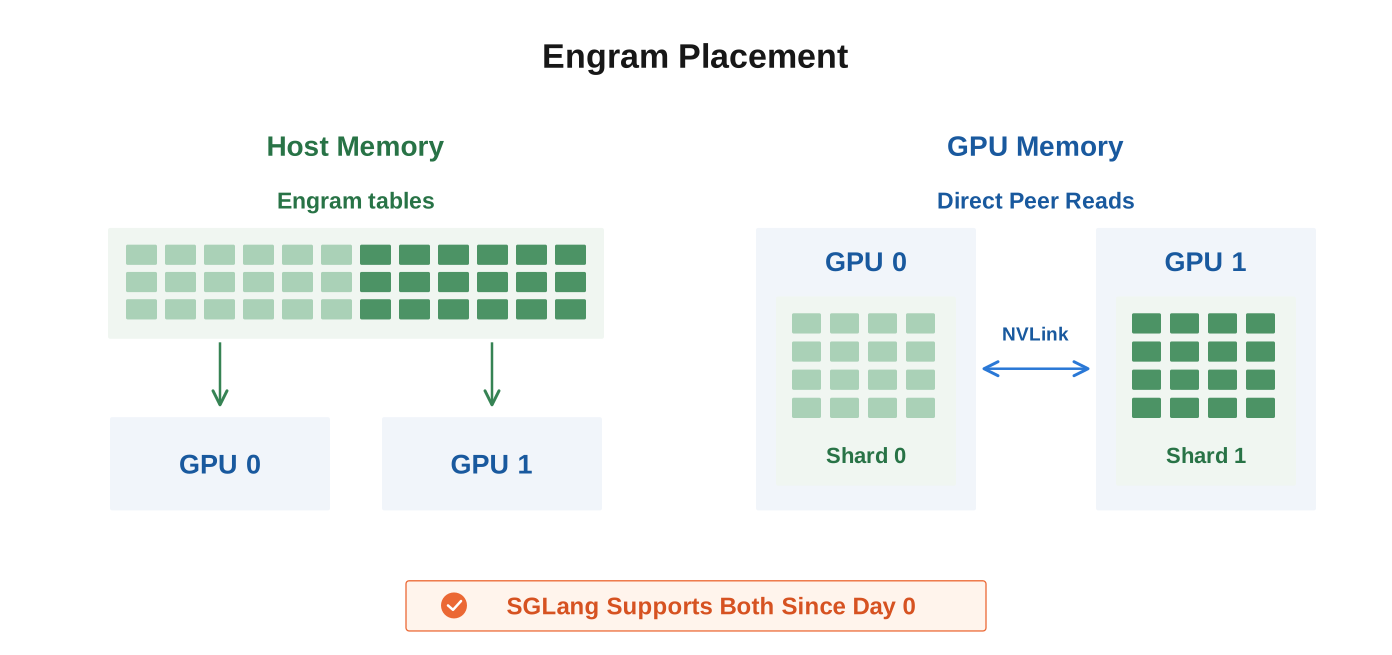
图 3:Engram tables 可放在 host memory,也可拆分到多张 GPU 并通过 direct peer reads 访问。
Zero-overhead scheduling
自 2024 年 12 月发布的 v0.4 起,SGLang scheduler 就会在 GPU 执行 step N 时,由 CPU 同步准备 step N+1,将调度开销与 GPU 执行重叠起来。DeepInfer 文档也将这一设计归功于 SGLang。
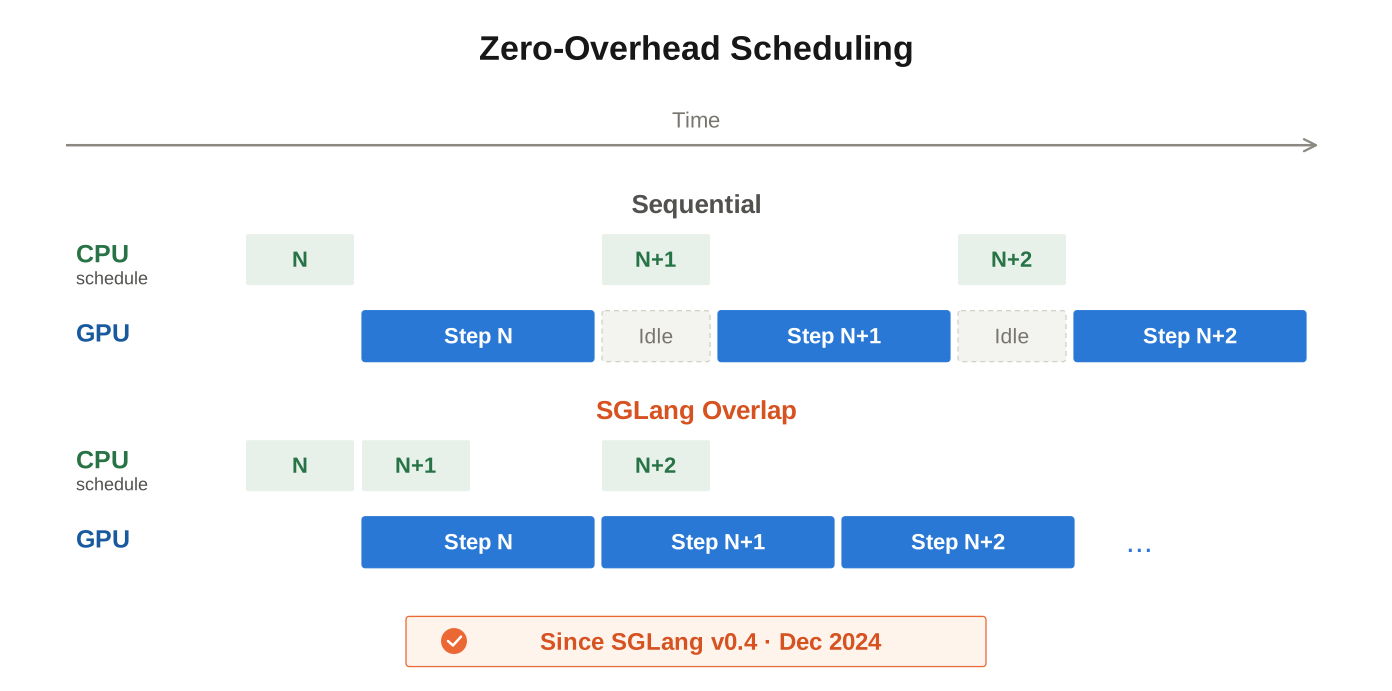
图 4:Zero-overhead scheduling,GPU 执行当前 step 时,CPU 准备下一 step。
DeepSeek chat format
SGLang 使用 DeepSeek 自家的 deepseek-recipe package 渲染 prompts 并解析 outputs,因此在 SGLang API 中,reasoning 与 tool calls 会遵循 DeepSeek 的格式。Grammar-constrained decoding 也支持 JSON schema、regex 和 EBNF。
Benchmark 结果
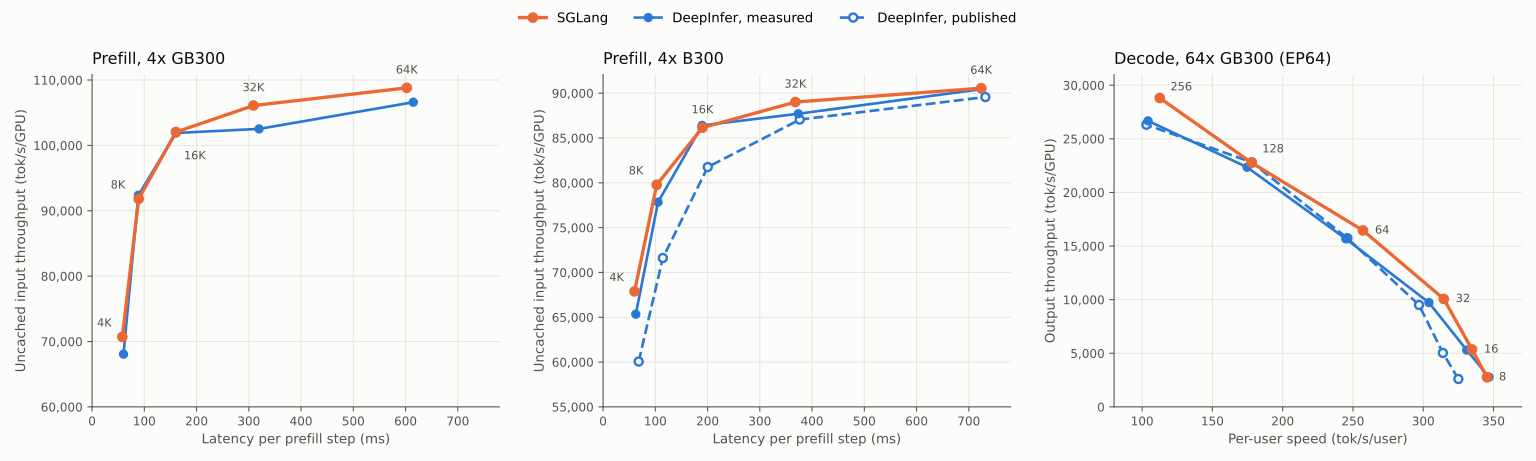
图 5:4x GB300 与 4x B300 上的 prefill,以及 64x GB300(EP64)上的 decode。
图中实线代表 SGLang 与 DeepInfer 的实测结果,虚线代表 DeepInfer 原始发布的 prefill 与 decode 结果,数值来自其公开图表读取。正文中的 prefill 对比采用实测 DeepInfer 曲线,并在每个测试点选取 DeepInfer 最快配置。
- Prefill,4x GB300:SGLang 的 prefill 吞吐最高达到 DeepInfer 的 1.04x;在每 GPU 每 step 4K、32K、64K new tokens 处领先,在 8K 与 16K 处基本持平。
- Prefill,4x B300:SGLang 同样最高达到 1.04x prefill 吞吐;在 4K、8K、32K 处领先,在 16K 与 64K 处持平。
- Decode,64x GB300(EP64):当每 GPU 请求数从 16 到 256 时,SGLang 的 step 时间缩短 1.1% 至 7.4%;在 8 requests/GPU 处与 DeepInfer 持平。
速度来自哪里
SGLang 的性能提升来自多项执行路径优化:Mega-mHC 可直接喂给 MegaMoE,attention 为 output projection 生成 MXFP8 输出,prefill compressor 与 request-window KV copies 使用 fused kernels。这些改动减少了中间内存流量,也减少了 kernel launches 数量。
此外,breakable CUDA graphs 覆盖了每 GPU 最高 8K tokens 的 prefill steps,包括长上下文与 data-parallel attention。Decoder replay 使用按 bounded suffix 尺寸配置的独立 graphs,因此即便大 prefill step 的其他部分以 eager 模式运行,这些 layers 仍可通过 CUDA graphs replay。
SGLang 额外补齐了什么
DeepInfer 的 README 提到,一个完整推理服务还需要三类组件,但其发布版本并未包含。SGLang 已经全部提供。
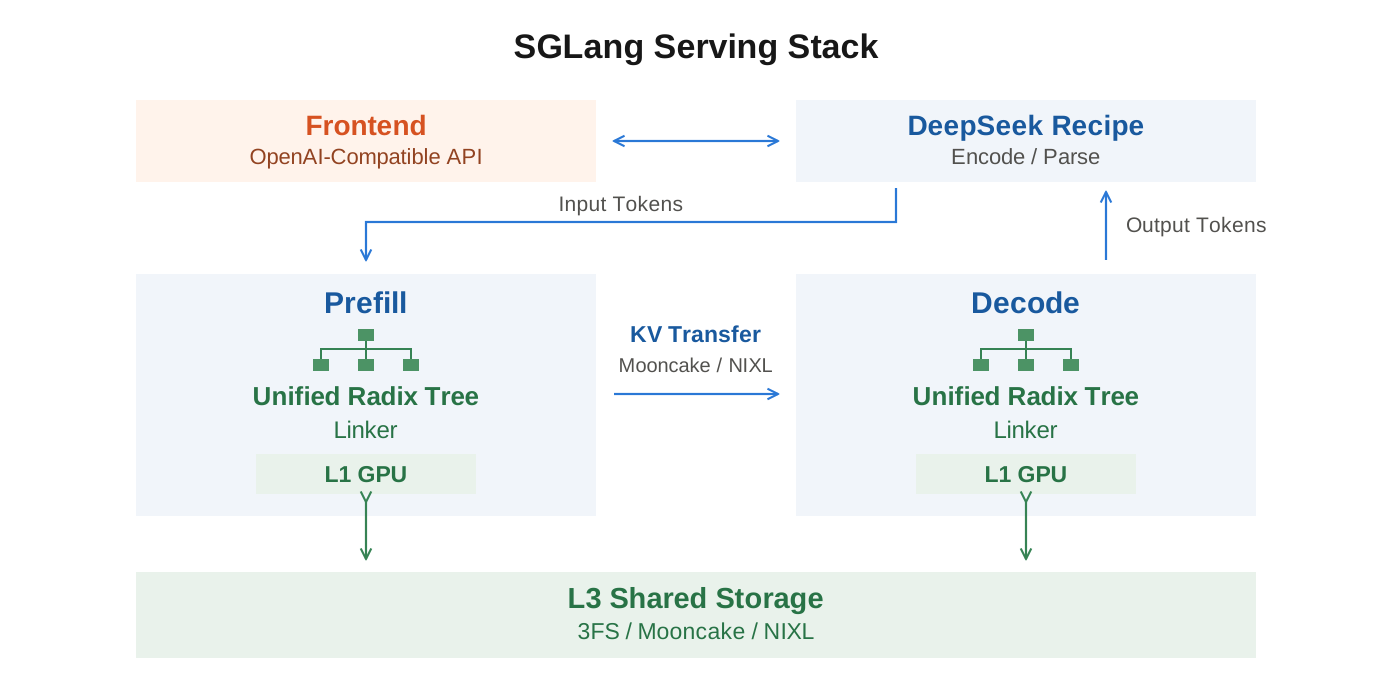
图 6:SGLang serving stack,Linker 将本地 L1 GPU caches 直接连接到共享 L3 storage。
KV cache system
SGLang 的 unified radix cache 可在请求之间、对话轮次之间复用 KV,也适用于这类 hybrid models。上图配置使用 Linker 将 L1 GPU caches 直接连接到共享 L3 storage,例如 3FS 或 Mooncake。对于需要 host-memory L2 tier 的部署,HiCache 也提供相应支持。
Prefill/decode disaggregation
SGLang 可将 prefill 与 decode 运行在不同服务器上,并允许用户选择 KV transfer backend,包括 Mooncake、NIXL 或 MORI。
跨副本负载均衡
SGLang 的 model gateway 可在多个 replicas 之间分发请求,并支持基于 cached prefixes 的路由,从而提升缓存命中与整体服务效率。
在这些能力之上,SGLang 本身也是一个 API server,支持 reasoning 与 tool-call parsing,并覆盖 NVIDIA GB300、B300、B200、H200 以及 AMD MI355X 等硬件平台。
Benchmark 设置
两套引擎均在相同硬件上运行 DeepInfer 自带 benchmarks。SGLang 在 prefill 测试中使用 commit 7d996300b9,在 decode 测试中使用 commit 3b95120f00;DeepInfer 使用 commit 774ce24。双方的启动命令与 benchmark clients 已通过 gist 提供。若用于真实模型服务,SGLang 团队建议参考其 DeepSeek-V4.1 cookbook;文中一些设置,例如 balanced expert routing,主要是为公平对比而存在。
Prefill 工作负载
prefill 使用 DeepInfer 的 prefill benchmark:每个请求包含 128K-token context 与 4K new tokens,每张 GPU 每 step 预填充 B 个 new tokens,B 的范围从 4K 到 64K。两套引擎运行在同一台 4-GPU 节点上,使用相同权重、DP4/EP4、balanced expert routing、关闭 EPLB,并配置 32 个 redundant experts。对于 DeepInfer,SGLang 团队在每个点选取其两种 Engram placement 中最快的结果进行对比。
致谢
SGLang 团队感谢 DeepSeek 开源 DeepInfer、FlashMLA、DeepGEMM 和 DeepEP,并详细公开其推理系统设计。这些工作为社区提供了清晰的性能基准,也推动了开源推理栈的持续优化。
© 2026 Winzheng.com 赢政天下 | 转载请注明来源并附原文链接